Yuma AI ranks #1 for accuracy and compliance in G2's AI CX Agent Evaluations
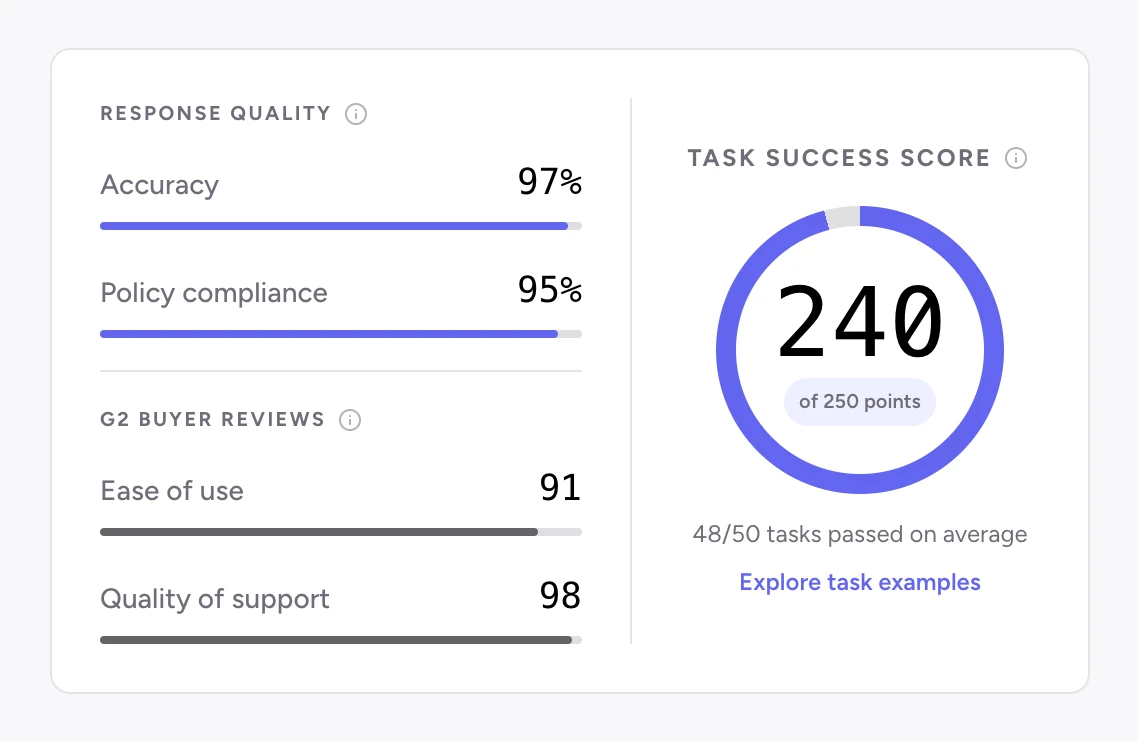
G2 put 10 AI customer service agents through the same 50 support tasks. Yuma AI ranked #1 for accuracy (97%) and policy compliance (95%), and #2 overall with 240 of 250 points.
1 / 4Yuma's scores in G2's AI CX Agent Evaluations
Key takeaways
Yuma AI ranked #1 for accuracy (97%) and #1 for policy compliance (95%) in G2's AI CX Agent Evaluations.
Yuma ranked #2 of 10 agents overall, with 240 of 250 task points and 48 of 50 tasks passed on average across 4 runs.
G2 set every agent up like a customer would, inside a simulated support company with a written policy and 38 working tools.
Accuracy checks whether the agent's claims are backed by evidence. Compliance checks whether it followed the written policy.
Yuma AI ranks #1 for accuracy and #1 for policy compliance in G2's AI CX Agent Evaluations, and #2 overall out of 10 evaluated AI customer service agents.
These scores don't come from reviews. G2 set Yuma up the way a customer would, gave it 50 support tasks, and graded what it said and what it did.
“
“Support leads don't lose sleep over the tickets AI can't answer. They lose sleep over the ones it answers wrong. If we could only pick two scores, we'd pick accuracy and policy compliance, and an independent test put us first on both.”
Guillaume LuccisanoFounder and CEO, Yuma AI
Yuma's scores in G2's AI CX Agent Evaluations
G2 ranks agents on task success, then reports accuracy and policy compliance separately for every agent. Here's where Yuma landed:
Score
Yuma
Rank of 10
What G2 measures
Accuracy
97%
#1
Are the agent's claims supported by evidence?
Policy compliance
95%
#1
Did the agent follow the written policy?
Task success
240 of 250 points
#2
How many of the 50 tasks the agent passed, at 5 points each
The next-best accuracy score among the 10 ranked agents was 96%. The next-best compliance score was 92%.
Across 4 runs of G2's 50-task dataset, Yuma passed 48 tasks on average. The agent ranked #1 overall scored 243 points, 3 more than Yuma.
G2 also ran two general-purpose AI models as baselines, with no support product around them. They scored 83% and 76% on accuracy. The gap is the product: the knowledge, actions and guardrails around the model.
See Yuma in action
See it live
Book a walkthrough of what's new, on your own setup.
G2 built a simulated support company for the test: realistic customers, account and order data, a written support policy, and 38 working tools for actions like refunds, subscription changes and account updates.
Then it configured each product as a customer would, using its knowledge base, actions, workflows and documented settings. Every agent got the same 50 tasks, drawn from buyer research, design partners and synthetic edge cases.
Each task produced a full transcript, a log of every tool call and the final state of the systems. That evidence was graded in two ways:
LLM judges scored accuracy, policy compliance and relevance against defined rubrics.
Deterministic checks confirmed the required outcome actually happened, like a refund issued or a subscription changed.
Vendors could flag setup mistakes before results went live, but couldn't change their scores. G2 keeps the full task set private so no one can tune for the test. The approach builds on the open τ²-bench method. The full methodology is on G2.
Why accuracy and compliance matter in ecommerce support
A wrong answer in support isn't a typo. It's a refund issued outside the return window, a delivery date nobody promised, or a discount nobody approved. Then someone on your team spends the afternoon cleaning it up.
Accuracy is whether the answer is true. Compliance is whether it follows your rules. You need both before you let an AI agent process returns and refunds on its own.
The Handbook. Brand pages set how Yuma sounds, Playbooks say what to do in each situation, and Procedures hold the exact steps. Where the Handbook is silent, Yuma doesn't improvise. It hands the ticket to a person on your team.
Hard Limits. Strict caps on refund amounts, coupon values, and loyalty points the AI can never exceed.
Gradual Rollout. Put a new playbook live on 10% of matching conversations, with the rest handled as drafts.
What the scores don't tell you
Yuma ranked #2 on task success, not #1. G2 also calls every evaluation a dated snapshot: it plans to refresh results several times a year and make the tasks longer and harder over time.
A simulated company also isn't your store. Your policies, your catalog and your edge cases are the real test. That's why you can start Yuma with a 30-day free trial on your own tickets, and why our case studies name the brand behind every result.
The evaluation sits alongside Yuma's Fall 2026 G2 High Performer badge, which comes from verified user reviews and a 4.8 out of 5 rating. One measures what customers say. The other measures what the agent does.


 Guillaume LuccisanoFounder and CEO, Yuma AI